Intel 18A vs TSMC N3E: What Panther Lake Teardown Reveals
A physical teardown of Intel’s Panther Lake processor by semiconductor research firm SemiAnalysis provides a detailed look at Intel 18A, the manufacturing process behind Intel’s latest generation of client processors.
The analysis examines the Intel Core Ultra 7 365 and investigates the transistor structures, interconnects, standard-cell libraries, and chiplet architecture used in the Panther Lake platform. Its findings offer an important assessment of Intel’s progress in advanced semiconductor manufacturing.
The central result is nuanced: Intel 18A achieves logic density comparable to TSMC N3E in the representative-cell comparison, but it does not establish an overall density advantage over TSMC’s newer N3P and N2 technologies or Samsung’s SF2 process.
The teardown also confirms that Intel has brought two major technologies into commercial consumer silicon: RibbonFET gate-all-around transistors and PowerVia backside power delivery. At the same time, Panther Lake demonstrates how modern processors combine multiple manufacturing nodes within a single package rather than relying on one process technology for every component.
These findings matter because semiconductor competitiveness cannot be reduced to process-node labels. Transistor density, power delivery, interconnect resistance, thermal behavior, manufacturing yield, and the physical layout of each functional block all influence the performance and economics of a finished processor.
🔬 1. Intel 18A Reaches TSMC N3E-Class Logic Density #
The most significant finding in the SemiAnalysis teardown is that representative compute logic manufactured on Intel 18A achieves approximately the same density as the TSMC N3E logic used in Panther Lake’s high-end GPU tile.
The result represents progress for Intel’s manufacturing roadmap, particularly because 18A incorporates a new transistor architecture and backside power delivery.
However, the finding must be interpreted within the scope of the measurement.
Representative-cell density and the 18.6% improvement #
SemiAnalysis reports that its representative standard-cell model places Intel 18A compute logic approximately 18.6% denser than the Intel 3 GPU logic used as the comparison baseline.
This is a comparison of measured logic implementations, not a statement that every circuit manufactured on 18A is 18.6% denser than an equivalent Intel 3 circuit.
The analysis also finds that the sampled Intel 18A compute logic and TSMC N3E GPU logic occupy a similar density range under its representative-cell model.
These findings suggest that Intel has made meaningful progress in fitting logic into a smaller physical area. Higher logic density can allow designers to integrate more functional units within a given area or reduce the silicon area required for a particular logic design.
However, the actual benefit depends on the circuit architecture and the constraints imposed by physical implementation.
How standard-cell geometry affects density #
The teardown examines characteristics such as standard-cell height, gate pitch, and local metal geometry to understand the density differences.
In the measured examples, Intel 18A uses a compact five-track logic-cell geometry, while the compared Intel 3 and TSMC N3E logic implementations use seven-track layouts.
The analysis finds that gate pitches are relatively similar across the sampled sites, making cell height a major contributor to the resulting density difference.
This illustrates why transistor density is not determined solely by the transistor structure. The standard-cell library, available routing resources, pin accessibility, power distribution, and timing requirements all influence how much logic can be placed in a given area.
Intel 18A’s backside power architecture helps separate portions of the power-delivery network from front-side signal routing, creating additional flexibility in local cell and routing design.
Why representative-cell density is not whole-die density #
A representative-cell model offers a useful way to compare logic-library geometry, but it does not describe the effective density of an entire processor die.
A real processor contains many different circuit types, each with its own physical requirements.
Important factors include:
- Standard-cell libraries and logic composition.
- SRAM macros and cache capacity.
- Analog and mixed-signal circuitry.
- Input/output interfaces and PHYs.
- Power-delivery networks.
- Signal routing and interconnect spacing.
- Timing constraints and placement utilization.
- Tile boundaries and packaging interfaces.
SRAM density, in particular, can significantly affect the area of a processor containing large caches. A design with dense logic but relatively inefficient memory macros may not achieve the same advantage at the complete-block level.
For this reason, the most defensible interpretation is that Intel 18A has reached TSMC N3E-class density in the specific representative logic comparison performed by SemiAnalysis.
🏭 2. Intel 18A Still Trails Newer Leading-Edge Nodes #
Although matching TSMC N3E in a representative logic comparison is a meaningful milestone, it does not establish that Intel has surpassed competing foundry processes.
SemiAnalysis reports that Intel 18A’s peak density remains below that of TSMC N3P, TSMC N2, and Samsung SF2 in the comparisons presented in its teardown.
This distinction is important because semiconductor process names do not correspond directly to identical physical dimensions, nor do they provide a universal ranking of density, power, and performance.
TSMC N3P and N2 #
TSMC N3E represents one implementation within the company’s 3nm-class process family. N3P is a subsequent development, while N2 introduces a newer transistor architecture based on nanosheet technology.
Consequently, reaching N3E-class logic density should not be interpreted as Intel 18A overtaking TSMC’s complete leading-edge roadmap.
The comparison also has methodological limitations. Different process technologies are often evaluated using different cell libraries, operating assumptions, SRAM designs, and circuit compositions.
A density advantage in one representative logic implementation does not necessarily translate into the same proportional advantage in a complete CPU, GPU, or accelerator.
Samsung SF2 as another comparison point #
Samsung SF2 provides an additional reference for evaluating Intel’s RibbonFET implementation.
Both technologies use gate-all-around transistor structures, but the particular transistor geometry, interconnect architecture, and process integration differ.
SemiAnalysis reports four stacked nanosheets in the examined Intel 18A RibbonFET implementation, compared with three stacked sheets in the analyzed Samsung SF2 configuration.
The number of stacked sheets is only one component of transistor design. Channel dimensions, electrostatic control, contact resistance, capacitance, and manufacturing process conditions also influence actual performance.
The takeaway is not that four sheets automatically produce a better transistor than three. Rather, the comparison shows how different manufacturers are implementing gate-all-around technology through distinct physical designs.
For additional context on the broader manufacturing competition, see PUDN’s comparison of Intel 18A and TSMC N2.
⚡ 3. RibbonFET and PowerVia Reach Commercial Consumer Silicon #
Panther Lake’s importance extends beyond logic density. It brings Intel’s RibbonFET transistors and PowerVia backside power delivery into a commercial client processor.
These technologies change two fundamental parts of semiconductor manufacturing: how transistor channels are controlled and how electrical power reaches those transistors.
RibbonFET: Gate-all-around transistor architecture #
RibbonFET is Intel’s implementation of a gate-all-around field-effect transistor (GAAFET).
Unlike a conventional FinFET, in which the gate surrounds multiple sides of a vertical fin, a gate-all-around design surrounds the channel more completely.
Intel’s RibbonFET implementation uses stacked horizontal nanosheets. The gate structure provides improved electrostatic control over the channel, helping manufacturers scale transistor dimensions while managing leakage and drive-current requirements.
Potential benefits include:
- Improved control of current through the channel.
- Greater flexibility in balancing performance and power.
- Continued transistor scaling beyond conventional FinFET structures.
- Improved control of leakage under appropriate operating conditions.
These benefits are not automatic. Actual results depend on the transistor geometry, materials, contact design, operating voltage, and surrounding process technology.
The architecture also introduces manufacturing challenges related to nanosheet formation, gate-stack integration, contact resistance, and process variability.
PowerVia: Backside power delivery #
PowerVia addresses another major scaling challenge: delivering power through increasingly dense integrated circuits without overwhelming the front-side routing network.
In a conventional design, signal routing and power distribution compete for space within the front-side interconnect stack.
PowerVia moves the principal power-distribution structure to the backside of the wafer, connecting it to the transistor-level circuitry through dedicated vertical interconnect structures.
This separation can reduce front-side routing congestion and improve power-delivery characteristics.
The SemiAnalysis teardown examines the physical implementation, including backside copper rails, vertical connections, and the materials used to integrate the power network.
The analysis also identifies trade-offs involving thermal resistance, capacitance, and manufacturing complexity.
Backside power delivery therefore should not be viewed as an improvement in every electrical metric. It changes the physical organization of the power network, creating opportunities for better routing and electrical performance while introducing additional process-integration requirements.
Why combining RibbonFET and PowerVia matters #
RibbonFET and PowerVia address different but complementary constraints.
RibbonFET changes the transistor structure to improve channel control. PowerVia reorganizes power delivery to reduce competition between power and signal routing.
Together, they give Intel a different set of design options for implementing dense, high-performance logic.
The significance of Panther Lake is that these technologies have progressed beyond laboratory demonstrations and process-roadmap announcements into production client silicon.
Their long-term competitiveness, however, will depend on the resulting balance of performance, power consumption, yield, reliability, and manufacturing cost.
🧩 4. Panther Lake Uses Multiple Manufacturing Nodes #
One of the most revealing aspects of the teardown is Panther Lake’s heterogeneous multi-tile architecture.
Rather than manufacturing every component on Intel 18A, Intel combines functional tiles produced using different process technologies and integrates them within a single package.
This approach allows each part of the processor to use a manufacturing process suited to its requirements.
The Intel 18A compute tile #
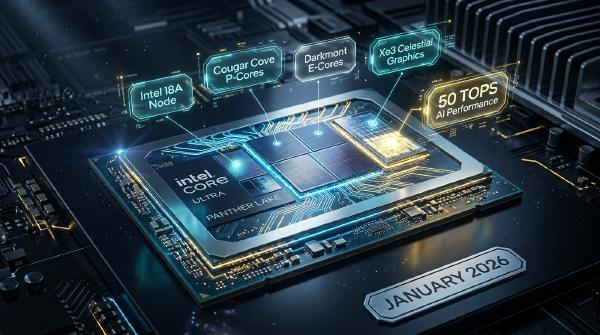
The main compute tile uses Intel 18A and contains the CPU cores and NPU 5 neural-processing engine.
This tile provides the clearest example of Intel’s latest transistor and power-delivery technology within the Panther Lake package.
CPU cores and neural-processing logic can benefit directly from improvements in logic density, transistor performance, and power delivery, although the resulting gains depend on the design and operating point.
The compute tile must also accommodate cache structures, memory interfaces, and internal communication resources. Its effective area therefore reflects more than the density of its logic cells.
The TSMC N3E GPU tile #
Panther Lake’s high-end GPU configuration uses a 12-core Xe3 GPU tile manufactured on TSMC N3E.
The lower-tier 4-core Xe3 GPU tile uses Intel 3 instead.
This creates an unusual but valuable comparison: two implementations of the same broad GPU architecture are manufactured using different process technologies within the same product family.
The arrangement demonstrates that a processor can combine Intel-manufactured compute logic with an externally manufactured GPU tile.
It also illustrates why process comparisons must account for the specific circuit being examined. The 12-core Xe3 implementation is not simply a larger version of the 4-core tile; its internal layout, cache organization, routing, and interface placement differ.
The TSMC N6 I/O tile #
Both I/O tile variants use TSMC N6 in the analyzed Panther Lake configurations.
I/O circuitry serves a different purpose from the leading-edge compute logic. PCIe and Thunderbolt interfaces must satisfy electrical, signaling, and compatibility requirements that do not necessarily benefit as much from the newest transistor technology as CPU logic does.
Using a mature process for these functions allows Intel to reserve the more advanced process for components where it may provide a greater benefit.
The larger I/O variant supports up to 20 PCIe lanes, while the smaller configuration supports a reduced set of connectivity resources.
The exact configuration depends on the processor SKU.
Foveros-S and heterogeneous integration #
The tiles are assembled using Intel’s Foveros-S packaging approach over a passive base tile.
This architecture separates the processor into functional blocks that can be designed, manufactured, and optimized independently before being combined into the complete package.
The potential advantages include:
- Choosing different manufacturing nodes for different functions.
- Reusing proven I/O designs.
- Scaling CPU and GPU configurations independently.
- Improving flexibility in product segmentation.
- Reducing the need to manufacture every component on the most expensive process.
The corresponding challenge is that each tile introduces physical and electrical integration requirements. Die-to-die interfaces consume area and power, add latency, and require careful floorplanning.
Heterogeneous integration is therefore not simply about combining the smallest available dies. The overall package must balance connectivity, manufacturing cost, performance, and thermal constraints.
For broader context, see KAD’s analysis of Intel Panther Lake, Core Ultra Series 3, and the 18A turning point.
🖥️ 5. GPU Tile Analysis: Intel 3 vs. TSMC N3E #
Panther Lake’s GPU configurations provide a useful opportunity to examine how manufacturing technology affects real circuit implementations.
The low-end GT1 tile contains four Xe3 cores and uses Intel 3. The larger GT2 tile contains 12 Xe3 cores and uses TSMC N3E.
Although both implement Xe3 graphics, their physical characteristics differ substantially.
Xe core area and process scaling #
SemiAnalysis reports that an Xe core in the Intel 3-based GT1 tile is approximately 69% larger than an Xe core in Lunar Lake’s GPU implementation and approximately 55% larger than a core in Panther Lake’s TSMC N3E-based GT2 tile.
These comparisons are specific to the examined tile designs and the area definitions used by the analysis.
They do not mean that every Intel 3 circuit is 55% larger than an equivalent N3E circuit. The measured block areas include logic, cache structures, and routing, all of which depend on architecture and physical implementation.
The gap nevertheless illustrates that manufacturing process choice can have a significant effect on the area required by a functional block.
At the same time, the GT2 implementation’s denser layout reflects more than transistor scaling. Cache organization, routing distances, timing targets, and the placement of shared resources also influence how much area each Xe core occupies.
Shared L1 and SLM capacity #
The teardown reports that Xe3 increases the combined L1 cache and shared local memory capacity from 192 KiB to 256 KiB, an increase of approximately 33%.
The corresponding area increases by only about 5%, indicating a substantial improvement in effective storage density within the measured implementation.
L1 cache retains data likely to be reused by a thread, while software-managed shared local memory (SLM) allows cooperating threads to exchange data efficiently.
Both mechanisms can reduce accesses to more distant memory resources, improving efficiency for suitable graphics and compute workloads.
However, larger shared memory capacity does not automatically guarantee better performance. Allocating more local memory to one thread group can limit how many groups reside on a compute unit simultaneously.
The benefit therefore depends on how the application uses the available storage and how the compiler schedules resources.
L2 cache organization #
The GPU tiles also differ in their L2 cache capacity and organization.
The Intel 3 GT1 tile contains 4 MiB of L2 cache organized into four 1 MiB banks. The TSMC N3E GT2 tile contains 16 MiB organized into eight 2 MiB banks.
The teardown finds that the N3E implementation uses SRAM macros storing 16 KiB each, compared with 8 KiB macros in the Intel 3 configuration.
The larger macros increase storage density by spreading some control and peripheral circuitry over more bits.
However, larger SRAM structures also introduce longer internal wires and different electrical characteristics. The design must balance density against access time, signal integrity, and power consumption.
The comparison reinforces an important point: cache density depends on SRAM architecture and macro organization, not only on the logic process used to manufacture the surrounding GPU.
🔮 6. Cougar Cove CPU Cores and NPU 5 Area Efficiency #
The teardown also examines the compute tile’s CPU and neural-processing components.
The results show how architectural changes and improvements in physical implementation can increase functionality without a proportional increase in silicon area.
Cougar Cove increases L2 cache capacity #
Panther Lake introduces Cougar Cove performance cores, evolving the Lion Cove architecture used in Lunar Lake.
According to the teardown, the Cougar Cove P-core occupies an area similar to the Lion Cove P-core while increasing its L2 cache capacity from 2.5 MiB to 3.0 MiB.
That represents a 20% increase in L2 cache capacity per core.
Maintaining a similar core footprint while increasing cache capacity is a useful example of how architecture and manufacturing technology interact.
However, additional cache does not automatically translate into a 20% performance improvement. The benefit depends on cache hit rates, access latency, workload characteristics, and the behavior of the memory hierarchy.
NPU 5 reduces area while maintaining INT8 compute resources #
Panther Lake also introduces Intel’s NPU 5 neural-processing architecture.
SemiAnalysis reports that NPU 5 occupies approximately 36.9% less area than NPU 4 in Lunar Lake while retaining the same number of INT8 multiply-accumulate (MAC) units.
The redesign reportedly consolidates processing resources and reduces the number of scratchpad memories and SHAVE digital signal-processing engines from 12 to six. NPU 5 also adds native FP8 support.
This is an important distinction between silicon area and advertised performance.
If an accelerator can retain a similar number of arithmetic units while reducing the surrounding circuitry and storage overhead, the recovered area can be used for other components or contribute to a smaller overall implementation.
The result does not establish that NPU 5 is 36.9% faster or more power-efficient in every workload. Those outcomes depend on clock frequency, memory access, data precision, utilization, and power management.
The teardown instead demonstrates a more specific improvement in the physical efficiency of the accelerator design.
🔥 7. The Physical Trade-Offs Behind Advanced Process Technology #
The Panther Lake teardown also highlights why process innovation cannot be evaluated using density alone.
The move to gate-all-around transistors, backside power delivery, and increasingly dense interconnects creates new engineering constraints that can offset some of the expected benefits.
Capacitance and interconnect resistance #
Reducing wire dimensions can increase resistance and make interconnect performance more difficult to manage.
At the same time, the electrical characteristics of neighboring wires, transistor contacts, and gate structures can influence capacitance and signal delay.
Manufacturers must optimize materials, geometries, and interconnect structures together to manage these effects.
The SemiAnalysis teardown examines several of these structures, including local metal layers, contact materials, vias, and the conductive paths used by PowerVia.
The findings illustrate how advanced process development involves many materials and integration decisions beyond the transistor itself.
Thermal resistance and backside power delivery #
PowerVia changes the location and structure of the power-distribution network, but thermal behavior remains a separate engineering concern.
Heat must still move through the transistor structures, interconnect stack, substrate, package, and cooling system.
Changes in the dielectric and metal structures can influence local thermal resistance, while increased power density can intensify hotspots.
The final thermal behavior depends on the complete stack and package rather than any individual manufacturing feature.
Manufacturing complexity and yield #
RibbonFET and PowerVia introduce manufacturing steps and integration requirements that differ from established FinFET designs.
The process must control nanosheet dimensions, gate-stack formation, contacts, backside alignment, and power-delivery structures with sufficiently low variability.
These requirements affect manufacturability, yield, reliability, and production cost.
A process with excellent theoretical density may still be commercially less attractive if it cannot achieve adequate yield or if its manufacturing costs erase the benefits of smaller devices.
This is why competitive process evaluation must include product-level performance and manufacturing economics rather than relying solely on standard-cell measurements.
📊 8. What the Panther Lake Teardown Actually Proves #
The SemiAnalysis teardown supports several conclusions about Intel’s current manufacturing position.
| Finding | Technical significance |
|---|---|
| 18A compute logic has density comparable to the examined N3E GPU logic | Intel has achieved competitive representative-cell density in this comparison. |
| 18A representative logic is approximately 18.6% denser than the Intel 3 GPU example | The newer Intel process improves density relative to the measured baseline. |
| N3P, N2, and Samsung SF2 remain ahead in the reported peak-density comparison | Matching N3E does not establish overall leading-edge density leadership. |
| RibbonFET and PowerVia are present in commercial Panther Lake silicon | Intel has moved these technologies into a shipping client product. |
| Panther Lake combines Intel 18A, Intel 3, TSMC N3E, and TSMC N6 | Heterogeneous manufacturing lets each functional tile use a different process technology. |
| NPU 5 occupies approximately 36.9% less area than NPU 4 while retaining the reported INT8 MAC count | Accelerator area efficiency can improve independently of nominal arithmetic-unit count. |
| The Xe3 GPU implementations differ significantly in core and cache area | Architecture, SRAM organization, routing, and process technology all affect block-level density. |
These findings do not establish that Intel has won the process race, nor do they imply that TSMC has a universal advantage in every aspect of manufacturing.
A complete comparison would also require detailed evaluation of transistor performance, power consumption, interconnect behavior, manufacturing yield, design rules, and the economics of building finished chips at scale.
The teardown’s most valuable contribution is its physical evidence: it replaces broad comparisons based on marketing names with measurements of actual structures inside a commercial processor.
🚀 Conclusion: Intel 18A Represents Progress, Not Process Dominance #
The Panther Lake teardown provides a detailed view of Intel’s effort to return to competitive leading-edge semiconductor manufacturing.
Its representative-cell comparison places Intel 18A compute logic near TSMC N3E GPU logic in density, while showing an approximately 18.6% improvement over the examined Intel 3 GPU implementation.
At the same time, the analysis indicates that TSMC N3P, TSMC N2, and Samsung SF2 remain ahead in the reported peak-density comparison.
The architectural findings are equally important. Panther Lake brings RibbonFET gate-all-around transistors and PowerVia backside power delivery into commercial consumer silicon, while its multi-tile package combines Intel and TSMC manufacturing technologies according to the needs of individual functional blocks.
The CPU, GPU, and NPU comparisons further demonstrate that process density is only one part of system design. Cache organization, local memory capacity, routing, power delivery, thermal behavior, and circuit architecture all contribute to the area and performance of the finished product.
The most defensible conclusion is that Intel 18A has reached a competitive level of logic density in the measured comparison and has demonstrated its new manufacturing technologies in a shipping processor.
Whether this becomes a lasting manufacturing advantage will depend on sustained progress in performance, power efficiency, yield, reliability, and cost.
Panther Lake marks a tangible step forward for Intel’s manufacturing roadmap, but the broader competition remains a multi-dimensional contest rather than a ranking determined by transistor density alone.