Google TPU 8tx and 8i Max: The Economics of Agentic Inference 13 November 2026·2884 words·14 mins Google TPU Ai Infrastructure Agentic AI AI Inference Confidential Computing KV Cache Cloud Computing
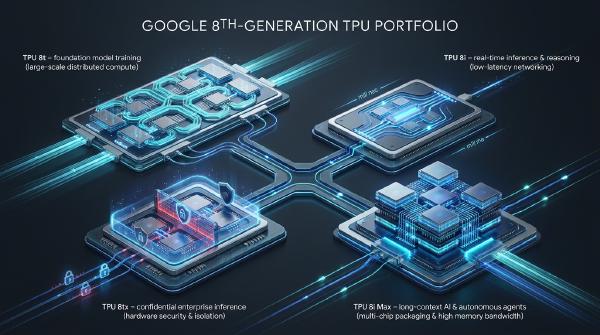
Google TPU 8th Gen: 8t, 8i, 8tx and 8i Max Explained 12 November 2026·3395 words·17 mins Google TPU AI Accelerators Ai Infrastructure Confidential Computing TPU 8tx TPU 8i Max Machine Learning Data Center Hardware
MT Forcing: Preserving Image Quality in Multi-Turn AI Editing 5 November 2026·2192 words·11 mins AI Image Editing Multimodal AI Diffusion Models Autoregressive Models Image Generation Machine Learning SenseTime HKUST
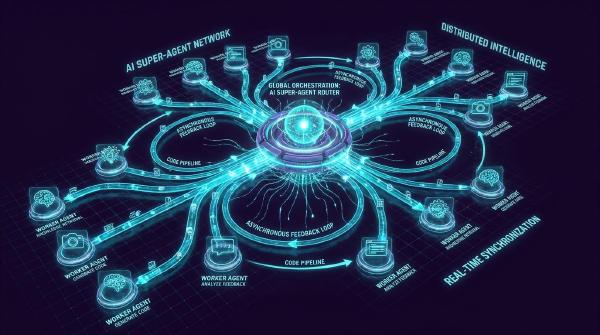
DeepSeek Super-Agent Explained: Multi-Agent Architecture and AI Automation 1 November 2026·5980 words·29 mins DeepSeek Super-Agent AI Agents DeepSeek Harness Multi-Agent Systems Agent Orchestration Autonomous AI Coding Agents Ai Infrastructure
Gemini 4 Carbon: Google Reclaims No. 1 on AI Intelligence Index 31 October 2026·3111 words·15 mins Google-Gemini Gemini 4 Carbon Google DeepMind AI Models Cybersecurity AI AI Agents LLM Benchmarks Artificial Intelligence
HP EliteBoard G1a Review: A Windows AI PC Built Into a Keyboard 30 October 2026·3450 words·17 mins HP EliteBoard G1a AI PC AMD Ryzen AI 300 Mini PC Copilot+ PC Mobile Workstation Hardware Review Hybrid Work
AMD and Meta Deepen AI Partnership: EPYC Venice, Helios and MI500 29 October 2026·3421 words·17 mins Amd Meta EPYC Venice AMD Instinct MI450 MI500 Helios Rocm Ai Infrastructure
SpaceX AI Infrastructure: 13GW Compute Ambition and $350B Expansion 29 October 2026·4966 words·24 mins SpaceX Ai Infrastructure Nvidia Colossus Data Centers AI Compute Power Infrastructure GPU Cloud Energy Storage
Edge AI GPU Convergence: Neural Rendering and On-Device LLMs 27 October 2026·4426 words·21 mins Edge AI GPU Architecture Neural Rendering On-Device LLMs Arm Mali NVIDIA RTX Qualcomm Adreno Imagination Technologies AI Hardware
NVIDIA GPU Unlock: RTX 4090 Tensor Core Throughput Doubles 27 October 2026·4141 words·20 mins NVIDIA GPU RTX 4090 Tensor Cores GPU Computing CUDA Open Source AI Inference GPU Performance Linux