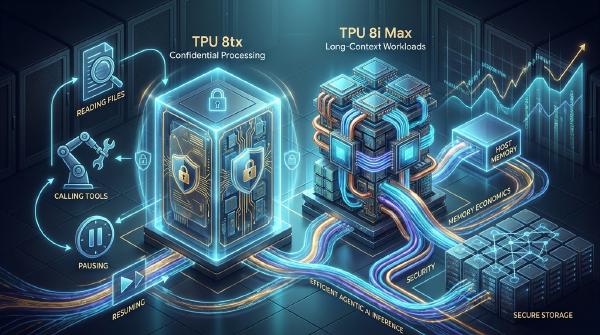
Google TPU 8tx and 8i Max: The Economics of Agentic Inference 13 November 2026·2884 words·14 mins Google TPU Ai Infrastructure Agentic AI AI Inference Confidential Computing KV Cache Cloud Computing
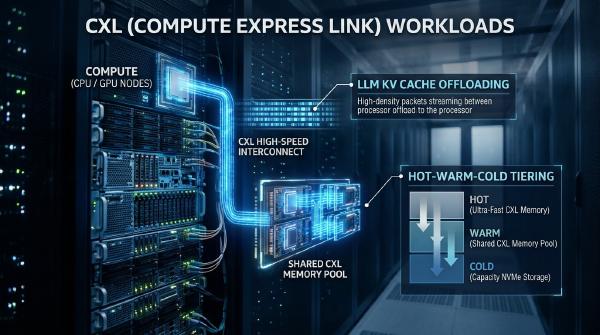
CXL Workloads: KV Cache, Memory Pooling, and Tiering 10 October 2026·3610 words·18 mins CXL Memory Tiering Llm Inference KV Cache Memory Pooling NUMA Linux Kernel Data Center Architecture
NVIDIA BlueField-4 CMX Targets Long-Context AI Inference 17 August 2026·1830 words·9 mins Nvidia BlueField-4 CMX Ai Infrastructure KV Cache Agentic AI Vera Rubin AI Storage Spectrum-X
Marvell CXL Switch Enables 48TB AI Memory Pools 12 August 2026·2229 words·11 mins Marvell CXL Ai Infrastructure AI Memory PCIe 6.0 KV Cache Data Centers Hyperscalers
Why Memory Bandwidth, Not Compute, Determines LLM Inference Speed 16 May 2026·493 words·3 mins Llm AI Hardware TPU Memory Bandwidth Mixture of Experts Inference Latency Large Language Models KV Cache Autoregressive Models AI Performance