Intel GPU D270 Targets AI Inference With 480GB LPDDR5X
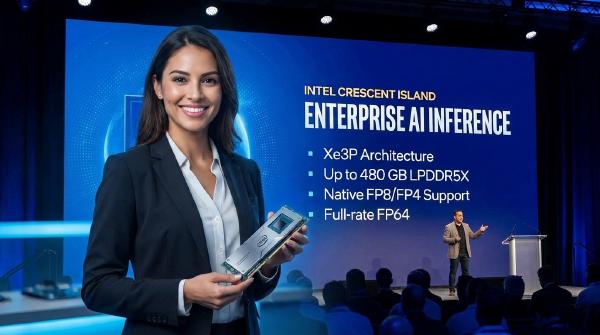
Intel has officially introduced its GPU D-series data center accelerators at the OCP Global Summit 2026, bringing the previously codenamed Crescent Island architecture into its commercial product lineup. Led by the flagship Intel GPU D270, the series targets enterprise AI inference, particularly memory-intensive workloads involving long context windows, concurrent requests, and multi-step agentic AI workflows.
The announcement establishes the product’s initial technical profile: up to 1.3 PFLOPS of peak FP8 compute performance, up to 480GB of LPDDR5X memory, and 1.5TB/s of memory bandwidth. The accelerator combines 32 Xe3P cores with 256 XMX matrix engines in a 350W, air-cooled PCIe 5.0 design.
Rather than competing exclusively on peak compute throughput, Intel is emphasizing memory capacity, deployment flexibility, and inference efficiency. These priorities reflect the changing requirements of production AI systems, where supporting larger model weights, longer prompts, and more simultaneous sessions can be as important as raw arithmetic performance.
The GPU D270 is designed for existing data center infrastructure, avoiding the need for proprietary interconnects or specialized liquid-cooling systems. Intel is targeting enterprise AI, software-as-a-service (SaaS), GPU-as-a-Service (GPUaaS), government infrastructure, and sovereign cloud deployments.
Customer sampling is underway, although Intel has not yet provided a definitive broad-release date or comprehensive pricing details. Initial specifications are available on the official Intel GPU D-series product page.
🧠 An Inference-First Architecture for Agentic AI #
Traditional data center GPUs often balance general-purpose compute with graphics-oriented capabilities, including rendering and ray tracing. Intel’s GPU D-series takes a different approach by reallocating silicon resources toward Xe3P compute cores and matrix engines.
The objective is to maximize useful compute for AI inference rather than preserve the full feature set required by graphics workloads.
Why agentic AI changes GPU requirements #
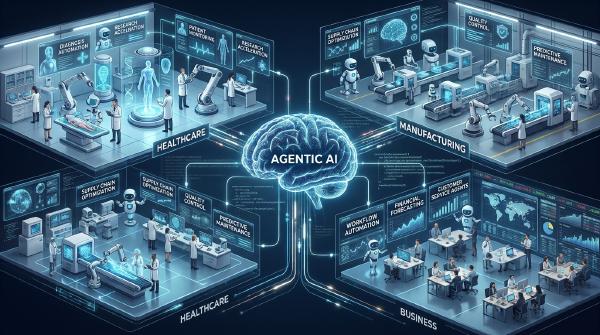
Agentic AI systems differ from conventional request-response applications because one user request can trigger a sequence of model calls, tool invocations, retrieval operations, and reasoning steps.
These workflows can produce several resource-intensive requirements:
- Long context windows: Agents must retain and process large amounts of conversational history, retrieved documents, code, and intermediate reasoning context.
- High prompt-processing demand: Large input sequences increase the computational work required during the prefill phase of inference.
- Concurrent sessions: Production services may run many independent agents simultaneously, increasing aggregate memory and compute requirements.
- Persistent model state: Models and associated inference state need to remain available across repeated requests to reduce reload overhead and maintain throughput.
As a result, raw compute throughput alone does not determine practical inference capacity. Memory availability, memory bandwidth, supported concurrency, and power consumption all influence the number of useful requests a server can sustain.
Intel’s D-series is designed around these constraints, with a particular emphasis on fitting more model data into local accelerator memory.
Reallocating silicon toward matrix computation #
The GPU D-series uses Intel’s Xe3P architecture, with 32 Xe3P cores and 256 XMX matrix engines in the D270.
Intel has shifted die area away from graphics and ray-tracing pipelines toward these compute resources. The design targets low-precision matrix operations used extensively in modern AI inference.
The resulting architecture is not intended to replace every general-purpose GPU. Instead, it aims to deliver an attractive balance of compute, memory capacity, power consumption, and deployment density for inference-heavy environments.
For workloads that do not require graphics rendering or the full functionality of a general-purpose accelerator, this specialization can avoid spending silicon on capabilities that provide limited direct value.
📊 Intel GPU D270: Hardware Specifications #
The D270 combines substantial memory capacity with a conventional PCIe accelerator form factor, positioning it for deployment in mainstream enterprise servers.
Core specifications #
| Specification | Intel GPU D270 |
|---|---|
| Product family | Intel GPU D-series |
| Former codename | Crescent Island |
| GPU architecture | Xe3P |
| Xe3P cores | 32 |
| XMX matrix engines | 256 |
| Peak FP8 compute | Up to 1.3 PFLOPS |
| Memory type | LPDDR5X |
| Maximum memory capacity | Up to 480GB per card |
| Memory bandwidth | Up to 1.5TB/s |
| Host interface | PCIe 5.0 |
| Board power | 350W |
| Cooling | Air-cooled |
| Primary workload | AI inference |
Specifications are based on Intel’s product information and the initial disclosure at OCP Global Summit 2026. Maximum memory configurations may depend on the specific board implementation.
FP8 performance and matrix engines #
The D270 delivers a stated peak FP8 compute performance of 1.3 PFLOPS. FP8 is an eight-bit floating-point format used in selected AI workloads to reduce data movement and computational requirements compared with higher-precision formats.
Lower-precision computation can improve efficiency, but actual performance depends on model support, numerical accuracy requirements, kernel implementation, and software optimization.
Peak FP8 throughput is therefore not a direct prediction of tokens per second. Real inference performance also depends on memory traffic, context length, batching, concurrency, and the efficiency of the serving framework.
The 256 XMX matrix engines provide the specialized computational resources intended to accelerate the matrix operations central to neural-network inference.
LPDDR5X memory and bandwidth #
The D270’s defining hardware characteristic is its support for up to 480GB of LPDDR5X memory.
Unlike accelerators that rely primarily on high-bandwidth memory (HBM), Intel’s design emphasizes a large memory pool while maintaining a conventional server power and cooling profile.
The specified bandwidth of up to 1.5TB/s is substantial for an air-cooled PCIe inference accelerator. However, it remains important to distinguish memory capacity from memory bandwidth.
Capacity determines how much model data and inference state can remain resident. Bandwidth determines how quickly data can move between memory and the compute engines.
A large memory pool can allow a larger model to fit on one accelerator, but it does not guarantee the highest token-generation throughput. Workloads dominated by repeated weight transfers may remain constrained by available memory bandwidth.
For a broader discussion of this trade-off, see KAD’s analysis of Intel Crescent Island’s Xe3P architecture and memory design.
💾 Memory Capacity Becomes a Competitive Differentiator #
The D270’s positioning reflects a broader change in AI accelerator design: inference deployments increasingly need to accommodate larger models and longer-running sessions without proportionally increasing the number of GPUs.
Fitting larger models on fewer accelerators #
Large language models require memory for model weights, intermediate activations, runtime data structures, and the key-value (KV) cache used during autoregressive generation.
Weight memory depends on parameter count and numerical precision. Quantization can substantially reduce the storage required, but additional memory is still needed for the runtime and inference state.
For example, a model containing 100 billion parameters would require approximately 50GB for its weights at an idealized four bits per parameter, before accounting for quantization metadata, runtime overhead, KV-cache allocation, and other data structures.
A 300-billion-parameter model would require roughly 150GB under the same simplified assumption. Actual memory requirements vary according to the quantization format and implementation.
With up to 480GB of LPDDR5X, the D270 can potentially accommodate considerably larger models or working sets than accelerators with more limited local memory.
Intel positions the platform for models with hundreds of billions of parameters on a single card and models exceeding one trillion parameters across multiple GPUs. The feasibility of a particular configuration depends on quantization, model architecture, context length, memory allocation, and how effectively the software distributes inference across devices.
Supporting longer contexts and concurrent inference #
Model weights are only part of the memory requirement.
During inference, the KV cache stores information from previously processed tokens so that the model does not need to recompute the entire context at every generation step. Its size increases with context length, batch size, model architecture, and the number of active sessions.
For a service handling dozens of concurrent users or autonomous agents, KV-cache capacity can become a significant system constraint.
A larger local memory pool can help retain more active sessions and longer contexts without frequently evicting state or distributing work across additional accelerators.
This is especially relevant for retrieval-augmented generation (RAG), coding assistants, document analysis, and agentic applications in which the input can include large volumes of retrieved information and conversation history.
However, memory capacity does not eliminate the need for efficient serving software. Scheduling, KV-cache allocation, batching, attention kernels, and memory bandwidth still determine how effectively the hardware supports simultaneous requests.
⚡ Standard PCIe 5.0 and 350W Air-Cooled Deployment #
Intel is also emphasizing the D-series’ deployment characteristics. The D270 uses a standard PCIe 5.0 interface and a 350W power envelope, with support for air-cooled server configurations.
This approach contrasts with accelerator platforms that depend on high-power modules, proprietary interconnect systems, or liquid-cooling infrastructure.
Reducing data center integration complexity #
A conventional PCIe form factor gives system builders a familiar starting point for integrating the D270 into existing server designs.
Potential advantages include:
- Simpler installation: Standard PCIe connectivity avoids the need for a proprietary host interface.
- Conventional cooling: A 350W air-cooled design can be easier to integrate into appropriately configured existing racks than a liquid-cooled accelerator platform.
- Deployment flexibility: Enterprise operators can evaluate the GPU within existing infrastructure rather than adopting an entirely new rack-scale system.
- Lower platform complexity: Standard server integration can simplify hardware qualification and deployment planning.
Compatibility is not automatic in every server. Operators still need to verify PCIe slot configuration, physical clearance, airflow, power delivery, firmware support, and system qualification.
A 350W accelerator also remains a significant power and thermal load. Dense multi-GPU installations require careful planning for rack power budgets and airflow even when liquid cooling is not necessary.
Scaling across multiple GPUs #
Intel expects the D-series to support multi-GPU systems using conventional server infrastructure. Tom’s Hardware reports that configurations scaling to eight GPUs are intended to support inference on models exceeding one trillion parameters.
Such deployments can increase aggregate compute capacity and memory resources. However, multi-GPU inference introduces additional requirements for model partitioning, communication, scheduling, and software coordination.
The practical benefit depends on whether the serving stack can distribute model weights and inference operations efficiently across the installed accelerators.
A large aggregate memory pool is useful only when the model runtime can make effective use of it.
🏢 Enterprise AI and Sovereign Cloud Use Cases #
Intel is targeting customers that need large-scale inference capacity without adopting highly specialized infrastructure.
Long-context RAG and document understanding #
Enterprise RAG systems retrieve information from internal documents, knowledge bases, and business applications before generating an answer.
As these systems ingest more source material, context windows and memory requirements can increase. The D270’s memory capacity could help keep larger models and longer-context workloads resident in accelerator memory.
Document understanding, contract analysis, technical support, and enterprise search are potential use cases, particularly where many users need to access the service concurrently.
The benefits will depend on the model, retrieval pipeline, context size, and inference software.
Coding assistants and agentic workflows #
Coding assistants frequently process source files, repository context, diagnostic logs, tool outputs, and test results. Complex requests may involve several rounds of retrieval and model execution.
Agentic workflows can amplify inference requirements because a single task may generate multiple model calls rather than one response.
The D270’s emphasis on memory capacity and prefill throughput is intended to support these repeated interactions. More resident model data and context may reduce some deployment constraints, while matrix compute engines accelerate supported operations.
Actual application performance will still depend on software scheduling, prompt length, decoding efficiency, and the number of concurrent tasks.
SaaS, GPU-as-a-Service, and sovereign AI #
The standard PCIe design and air-cooled profile also target service providers that need to deploy accelerators across multiple servers or customer environments.
SaaS providers may use the hardware to deliver inference as a managed service. GPUaaS operators may expose accelerator capacity to multiple customers, while governments and sovereign-cloud operators may prioritize control over deployment location and infrastructure configuration.
These markets place demands on security, isolation, reliability, software support, and predictable operating costs in addition to raw compute performance.
The D270’s commercial success will therefore depend on more than its hardware specifications. Intel will need to demonstrate competitive end-to-end inference performance and establish a software stack that customers can deploy and maintain reliably.
🧰 Software Ecosystem and Linux Support #
Accelerator hardware depends on a complete software stack encompassing drivers, runtime libraries, compiler support, model frameworks, optimized kernels, and production-serving tools.
Intel is positioning the D-series around a common Xe software foundation and says the platform is designed to work with leading frameworks, including vLLM and the open PyTorch ecosystem.
These integrations are important because enterprise customers generally want to adapt existing AI applications rather than rewrite model-serving software for a new accelerator.
Upstream Linux development #
Phoronix reported on October 12, 2026, that Linux driver development for Crescent Island was progressing well in the upstream kernel process. The publication expects the upstream support to be in a strong position by the time the accelerators ship at scale.
This is an encouraging sign for customers that prefer standard Linux infrastructure and open-source driver development.
Nevertheless, upstream progress should not be confused with a guarantee that every hardware function, distribution, framework, and deployment configuration will be fully supported at launch.
Production readiness also depends on runtime maturity, kernel and compiler compatibility, model coverage, monitoring tools, and ongoing performance optimization.
Performance still requires independent validation #
Intel has disclosed important architectural specifications, but independent end-to-end benchmarks remain necessary to establish the D270’s practical performance.
Useful evaluations will need to measure more than peak FP8 throughput. They should include:
- Prompt-processing throughput: How quickly the accelerator handles long input sequences during prefill.
- Token-generation speed: How efficiently it produces output during the decode phase.
- Concurrent-session capacity: How throughput and latency change as the number of active requests increases.
- Memory efficiency: How many model weights and KV-cache entries can be retained under real serving configurations.
- Performance per watt: How much useful inference throughput is delivered within the 350W power envelope.
- Software portability: How effectively existing models and serving frameworks run on the platform.
Comparisons with competing inference accelerators will also need matching model configurations, quantization methods, batch sizes, context lengths, and latency targets.
Until those results are available, the D270 should be evaluated primarily on its disclosed hardware characteristics and deployment approach rather than assumed to outperform competing products.
🔎 Competitive Positioning: Capacity, Bandwidth, and Deployment Cost #
The GPU D-series enters a market in which accelerator vendors are pursuing different balances among compute density, memory bandwidth, memory capacity, power consumption, and system complexity.
Some platforms emphasize extremely high HBM bandwidth and rack-scale interconnects. Intel is pursuing a different balance with substantial LPDDR5X capacity, a conventional PCIe interface, and an air-cooled power profile.
This distinction does not make the D270 universally superior or inferior to HBM-based accelerators. It makes the platform relevant to a particular set of inference requirements.
Where the D270 may fit #
The D270 is potentially attractive when model capacity, context length, concurrency, and deployment simplicity are important constraints.
A deployment that needs to keep large model weights and many inference sessions resident may value a larger memory pool, even if another accelerator offers greater peak memory bandwidth.
Conversely, workloads that are highly sensitive to data-movement throughput may favor accelerators with higher bandwidth, depending on their model and execution characteristics.
The relevant comparison is the cost of delivering a completed task or token at the required latency and concurrency—not memory capacity or peak FLOPS in isolation.
What remains unknown #
Several factors will determine the D-series’ commercial position:
- Product pricing and total system cost.
- The actual memory capacity offered by each card configuration.
- Independently measured inference performance across different models.
- Availability and maturity of optimized software.
- Server-vendor qualification and volume shipment schedules.
- Power efficiency under sustained production workloads.
These details will determine whether the D270 can translate its memory-rich design into lower operating costs and a compelling alternative for enterprise inference.
✅ Conclusion: Intel Bets on Memory-Rich, Air-Cooled AI Inference #
Intel’s GPU D-series marks the transition of Crescent Island from a development codename into a formally named inference-accelerator product family. The flagship D270 combines 32 Xe3P cores, 256 XMX matrix engines, up to 1.3 PFLOPS of FP8 performance, up to 480GB of LPDDR5X memory, and 1.5TB/s of memory bandwidth in a 350W air-cooled PCIe 5.0 design.
Its main differentiator is not peak compute throughput alone. Intel is targeting AI workloads that must accommodate large models, long contexts, and multiple concurrent sessions without requiring a specialized liquid-cooled infrastructure stack.
The approach could be attractive for enterprise RAG, coding assistants, document understanding, SaaS inference, and sovereign AI deployments. A larger local memory pool may allow these workloads to operate with fewer accelerators in some configurations, while standard PCIe connectivity and conventional cooling can simplify integration.
However, the final value proposition remains dependent on software maturity, real-world inference performance, pricing, product availability, and the memory configuration offered by system vendors. The announced specifications provide a promising technical foundation, but they do not yet establish a universal performance or cost advantage over competing accelerators.
For Intel, the GPU D-series represents an attempt to compete in AI infrastructure through a differentiated balance of memory capacity, power efficiency, and deployment flexibility. Its ability to turn those design choices into reliable, cost-effective inference services will determine whether Crescent Island becomes a meaningful option for production AI data centers.